I feel like the paper itself does a fairly good job:
> The [k-server] problem’s definition is simple: There are k servers located at points of
a metric space. At each time step, a request arrives at a point of the metric space. An online
algorithm must serve the request immediately by moving a server to the requested location, without
knowledge of future requests. The goal is to minimize the total distance traveled by servers.
> The k-server conjecture states that a deterministic online algorithm can achieve competitive
ratio k on every metric space.
I only had to look up what "competitive" means in this context, and wikipedia [0] had this to say about it:
> An algorithm is competitive if its competitive ratio—the ratio between its performance and the offline algorithm's performance—is bounded.
The ratio by which this performance is bounded for a k-competitive algorithm is k (plus some constant) [1]. We can consider the analogy of k support technicians ("servers) located in different (physical) locations ("in metric space"): The conjecture/theorem states that in any metric space (Not necessarily two- or three-dimensional), there exists an online algorithm that results in travelled distances of no more than roughly k times that of the optimal distance if all requests were known in advance.
I’d be shocked if anyone with any kind of post-secondary education in any numerate discipline couldn’t give you at least an informal definition of a metric space. Certainly all the physicists, all the geneticists, all the ML people.
I should have added "for a technical paper". They are generally not written for five year olds, and "metric space" is a term I've seen introduced anywhere between semesters 1 and 3 in most technical Bachelor's degrees.
I take ELI5 in hackernews comments to mean: "Explain like i'm someone with a vaguely technical background but no knowledge in this particular field", not "I'm a literal five year old". I think it's probably close to impossible to explain this adequately to an actual five year old while staying true to the essence of the paper.
I would expect someone commenting ELI5 on Hacker News to mean that they didn't understand the article directly, so pasting several paragraphs verbatim is not particularly helpful to them. If you think that the article is clear, and they're still asking for clarification, it's a sign that you've probably overestimated the clarity to someone with less experience in the subject (as always, relevant xkcd for this: https://xkcd.com/2501/)
That's fair, I had assumed they hadn't read the article at all ;) If they have, it would have been nice to know which parts of the problem definition the paper describes as "simple" they struggled with, otherwise I default to "I haven't read the article and would like a summary for a technically inclined layman"
I would expect someone who says ELI5 to have found pretty much all of it hard to understand. The paper calling something "simple" is either them talking to other experts or an instance of the same phenomenon I called out where experts vastly underestimate how approachable things are to non-expert. At least personally, I had never heard the term "metric space" before. I assumed it didn't mean "three dimensional space measured in units that are an exponent of meters", but I didn't know how to tell the difference between whether it was a specific nuanced mathematical concept or if it just meant "space that can be measured". I could google it, but when I have to do that before I've gotten through the first sentence that the paper describes as "simple", it does not give me any confidence that the paper is written with an audience like me in mind.
> Die Lösung müsste eigentlich mit Hilfe des Buches zu finden sein (..who worthily will hear or read this book..)
And there’s another one that says:
> jeweils 32 zahlen pro reihe.
erste zeile seitenzahl
zweite zeile wort?
oder umgekehrt?
wär mir als erstes in den sinn gekommen.
leider gerade keine zeit das nachzuschauen.
So people have seen and proposed the method already in 2014 that it’s keyed to the book but had not had time to pursue a solution.
its not quite the correct method though, the commenter suggests using the first row as a page index, and the second row as the word index, but the actual solution was using both rows as word indices within the 32 paragraphs ("Proquiritations") paired to the 32 numbers in each row
It is actually the correct method but not the correct solution. Nevertheless, the claim is not that this is the correct solution, nor that matters for the point being made.
Thank you, and SahAssar for doing the due diligence here. Like many others, I have at least a passing interest in cryptography, and I'm confident I'd never even heard of this before.
Is it wrong to presume they tried to run a similar prompt on all ciphers that come before this one in search results, and this was the only one that worked?
Because in academia, your name and your body of work is a big deal that can open or close doors, and assigning credit is an important part of it. This isn't a new thing/exclusive to the AI era either.
I haven't played it myself, but surely an article written one month after the game's release doesn't do it justice, considering there have been multiple major updates attempting to address the gripes players initially had with the game in the 10 years since then (And review trends on steam indicate that these attempts were successful)
They've added a lot of elements inspired by other games. One of the first things they added was base-building. Also a colony sim subgame, a pokemon-like subgame, fishing and cooking subgames, a roguelike subgame (exploring derelict dreadnought spaceships), as well as a lot more non-procedurally generated storyline/quests.
The worst thing I can say about it is that it tries to be everything for everyone, and is relentlessly friendly - all the new mechanics are very forgiving, very optional and (from what I've seen) rather easy. But there is sort of an in game story explanation for why it sometimes feels more like Stardew valley than a space exploration game.
The original massive controversy was the founder of the studio claiming it had multiplayer when it very clearly didn't which was such an odd thing to claim and easy to prove false.
That and the trailer was very different than the released game.
They apologized IIRC and then continued to work on it for like a decade - adding multiplayer and many large changes to the game
Unfortunately, given the sheer magnitude of text on the internet, we need heuristics to gauge whether something is worth reading or not.
For authors/blogs that I don't yet know, LLM-generated text is a clear anti-signal for me, and Pangram has been very useful in that regard.
False positives (Pangram labels something slop that isn't) I'm not that worried about, since the worthwile articles generally circle back to me some way through the communities I'm involved in, so I like to err on the side of not instantly reading something anyways.
For false negatives, that depends on the type of article at hand. If an error leads to me spending 2 minutes reading an article that ended up being not worth reading I'd be fine with an order of magnitude more than if false positives happen on articles that take 30 minutes to go through. Maybe on the order of 1-3% overall?
In a rug pull, the thing you own (usually some kind of digital asset) goes down in value, leaving you with less money than you started with, whereas theft leaves you no longer possessing the asset itself.
A few extra steps. Usually, the rug pull doesn't involve directly taking something that belongs to other people, but instead, selling your own thing in a dishonest way.
> Are there any regular typing keyboards with velocity sensitive keys? I genuinely don't know
Yes, a number of the mechanical keyboards that use Hall effect switches let you access the velocity data. Wooting has an official SDK, and there are community-supported drivers for a number of Keychron boards
Yeah, velocity definitely jumped out at me as a difference, but it seems(?) like being velocity-sensitive could 2x the cost, maybe even 3x, but not 10x ¯\_(ツ)_/¯
I'm absolutely not calling it over-priced, just puzzled.
Well the only moving part in a typing keyboards is a mass-produced switch that you slot into a PCB. There are mass-produced hall effect switches that can provide velocity sensitivity, but it's a pretty distant comparison. The keys on a lumatone aren't anything like buttons; they're weighted mechanical arms with significant travel -- much more like a piano key than a keyboard key. And it has 280 of these! The degree of mechanical hardware in this thing makes it seem not really comparable to a PCB with some switches slotted into it.
That said! There are people making DIY isomorphic keyboards using hall-effect keyboard switches. None are commercially available right now, but see e.g. the MidiHex at https://gullsonix.co.uk/. You could make one for a fraction of the cost of a lumatone -- but of course it would be a very different instrument.
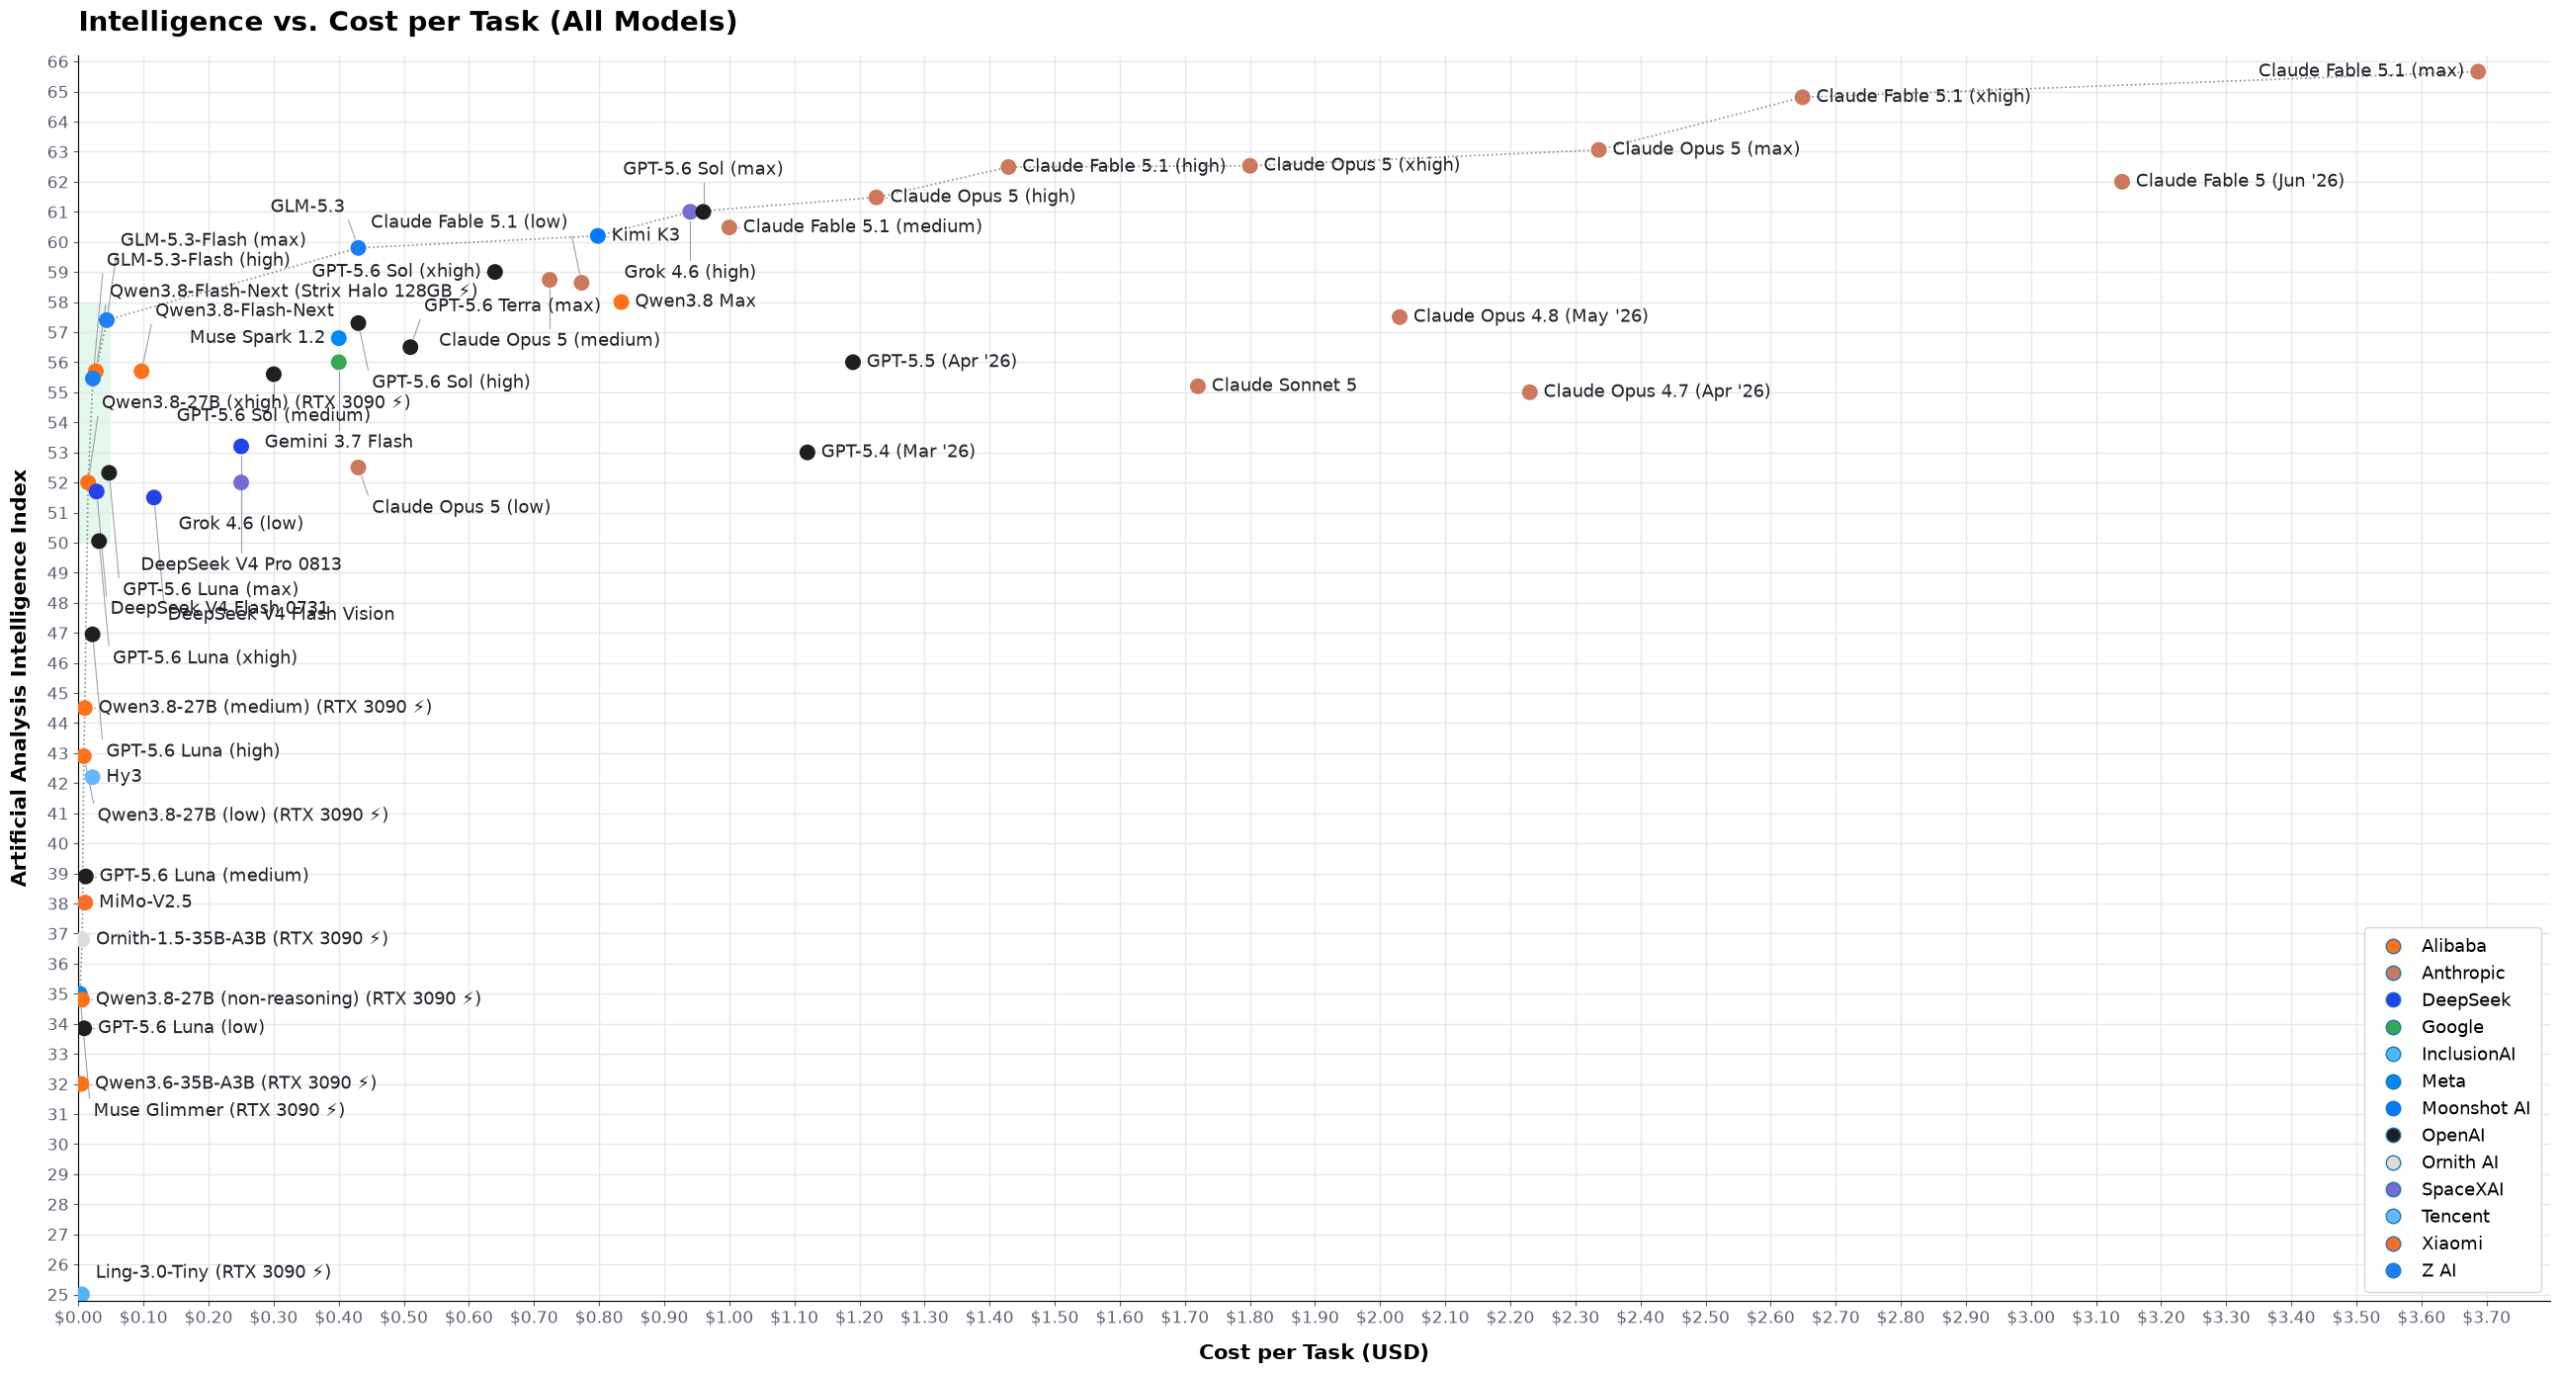
> The first issue I have with it is that it uses a logarithmic scale on the cost axis. Using a log scale is the only way to make you spot the difference between a model that costs $0.015 per task and one that costs $0.032, while the same plot contains a model that costs $3.69 — almost 250 times as expensive. However, the net result is that the viewers can no longer appreciate the immensity of the price difference between the cheap models and the heavy ones; nor can they realize how inconsequential the price differences are between the cheap models.
This is an asinine complaint, and nobody can seriously tell me that the last plot on their page [0] is more readable than the AA one [1]. If I'm using a model at the lower range of the cost scale for whatever list of tasks, and i switch to another model at the lower end of the cost scale, my spending might double anyways! This should be reflected in the plot, and linear scale doesn't do it justice.
It's also much easier to see the mentioned pareto frontier in the log plot than in the linear one.
I can see why they disagree with the pricing determination for open/local models, but I don't think there is one clear right way to do it. So how do they do it instead?
>Hardware is priced at zero, on the basis that both an RTX 3090 PC and a 64GB Strix Halo are desirable gaming/work machines anyways.
...oh
Would have been nice to mention explicitly how the pareto frontier changes with those new calculations.
It’s funny they state log plot is “the only way” to keep the cheap area readable, say they hate it, and then immediately have to zoom into their non-log plot cheap area because it’s unreadable.


> The [k-server] problem’s definition is simple: There are k servers located at points of a metric space. At each time step, a request arrives at a point of the metric space. An online algorithm must serve the request immediately by moving a server to the requested location, without knowledge of future requests. The goal is to minimize the total distance traveled by servers.
> The k-server conjecture states that a deterministic online algorithm can achieve competitive ratio k on every metric space.
I only had to look up what "competitive" means in this context, and wikipedia [0] had this to say about it:
> An algorithm is competitive if its competitive ratio—the ratio between its performance and the offline algorithm's performance—is bounded.
The ratio by which this performance is bounded for a k-competitive algorithm is k (plus some constant) [1]. We can consider the analogy of k support technicians ("servers) located in different (physical) locations ("in metric space"): The conjecture/theorem states that in any metric space (Not necessarily two- or three-dimensional), there exists an online algorithm that results in travelled distances of no more than roughly k times that of the optimal distance if all requests were known in advance.
[0] https://en.wikipedia.org/wiki/Competitive_analysis_(online_a...
[1] https://www14.in.tum.de/personen/albers/papers/brics.pdf Section 1.1
reply